Research Area
We build learning systems that see, remember, and reason reliably by grounding them in signal-processing and mathematical structure. Our roots are in inverse problems for imaging (sparse recovery, compressed sensing, deep networks for reconstruction); today the work spreads over three connected directions, summarized below with our latest results. The full list is on the Publication page.
1. World Models and Agents
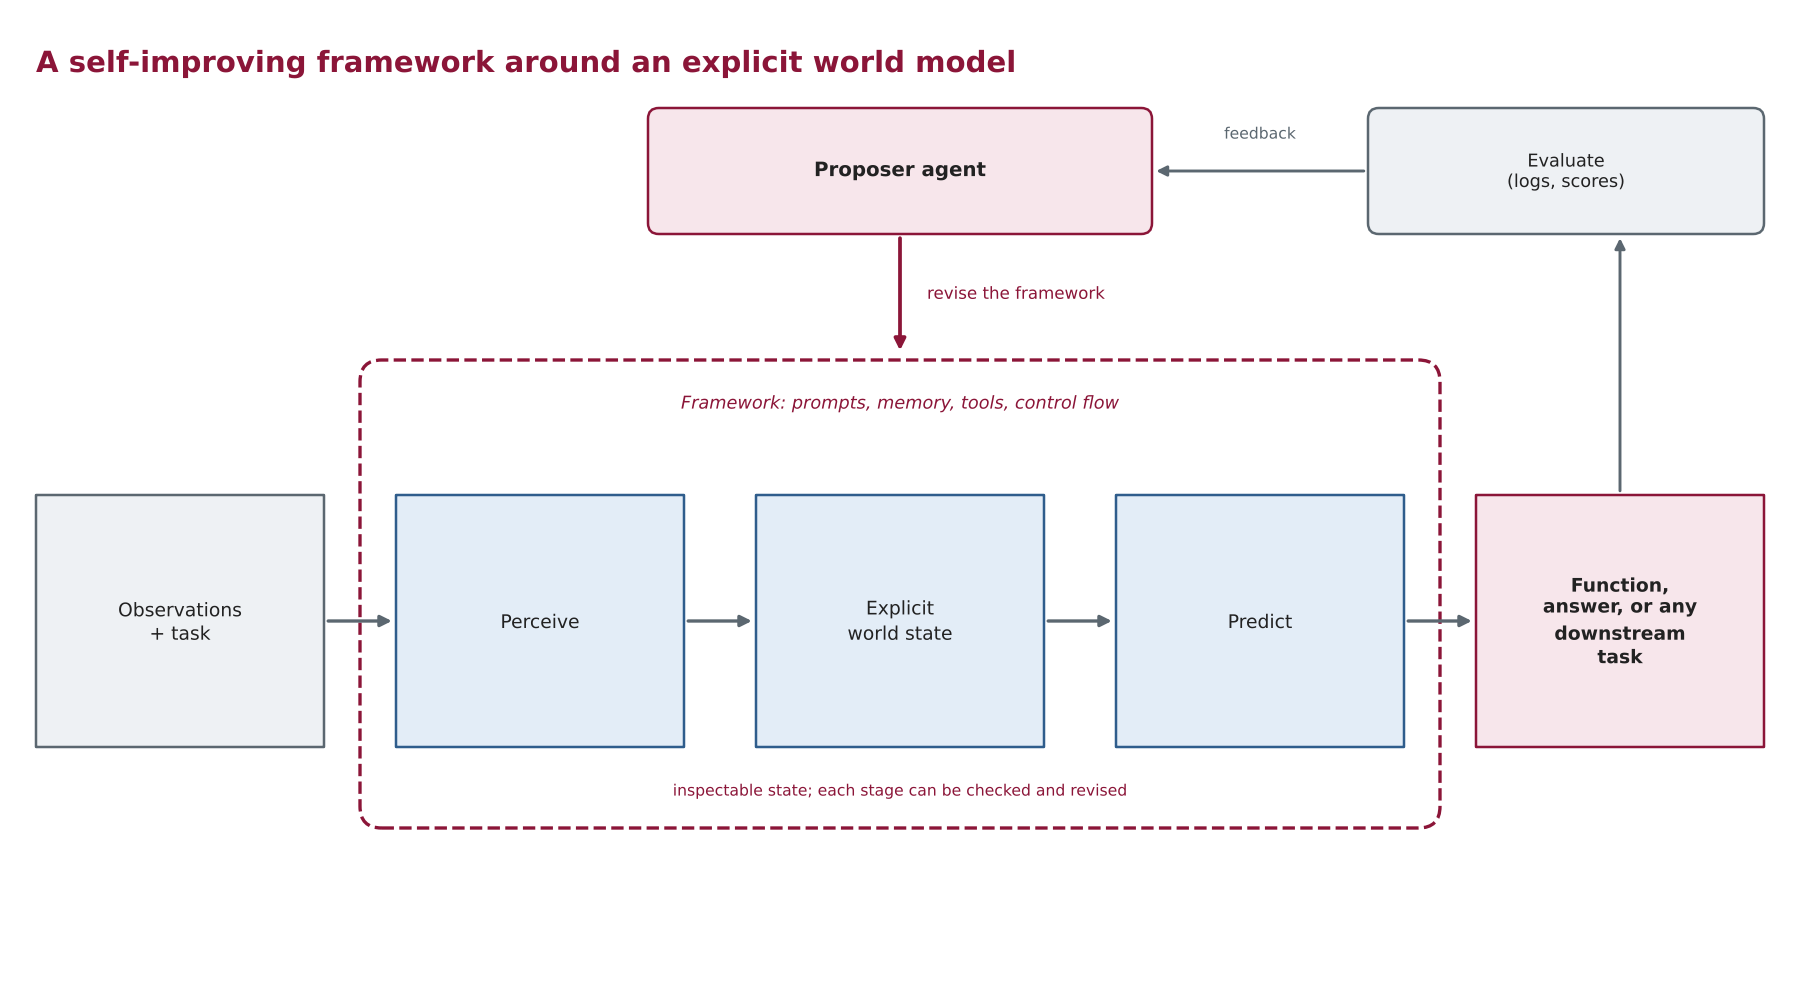 |
We study world models that make multimodal agents reliable. Errors in downstream tasks such as function prediction and multimodal understanding often share one cause: the model's internal state does not faithfully represent what was observed. We make that state explicit. An agent perceives the observations, writes them into an inspectable world state, predicts how the state evolves, and conditions its output on it, whether that output is a function, an answer, or any other downstream task. Instead of hand-designing this pipeline, we treat the framework around the model (its prompts, memory, tools, and control flow) as the object of optimization: a proposer agent revises the framework from execution logs and evaluation scores, so the framework improves, not only the model. The same view extends to continual learning with memory and to inputs beyond RGB, such as hyperspectral imaging, where RGB-centric vision-language models fall short.
Latest results.
Bayesian model discovery with language models (arXiv 2026). An explicit-hypothesis world model for science: an LLM proposes candidate model families, a numerical engine fits them and weighs them by model evidence, and the next experiment maximizes the expected information gain over families and parameters. Fits and residual diagnostics return to the LLM, which closes the loop between hypotheses and experiments. On four scientific-discovery benchmarks it beats in-context learning and LLM-based scientific agents, and explicit fitted models cut error 4.7x in an ablation.
2. Generative Diffusion Models
 |
We use diffusion models as priors for restoration and controlled generation, and ask how to inject knowledge, steer sampling, and measure the result.
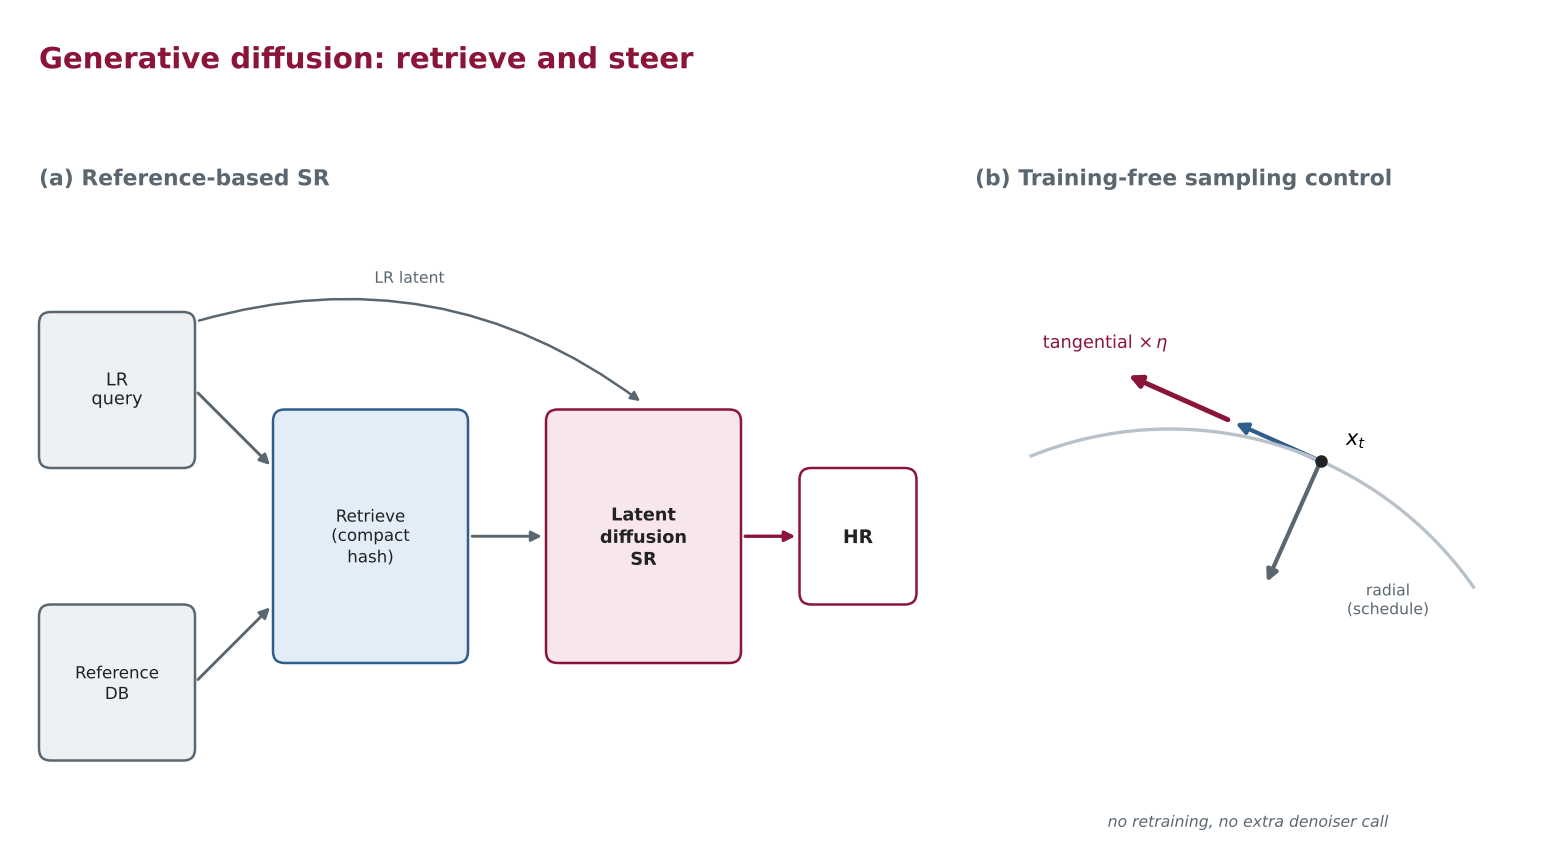
Reference-based super-resolution. iRAG (ICCV 2025) retrieves look-alike high-resolution images with a compact binary hash from a large, diffusion-augmented database and feeds them to a latent-diffusion SR model. ReAL (ECCV 2026) introduces a reference-to-image (R2I) aware latent diffusion.
Training-free sampling control. TAG (ICML 2026) splits each update into radial and tangential parts and amplifies only the tangential part, with no retraining and no extra denoiser call; unconditional FID on SD v1.5 drops from 58.41 to 46.20 (project). A Hopfield view of attention (ICML 2026) treats the symmetric part of the attention logits as an energy and the skew part as a circulation knob that trades fidelity against diversity (project). Related guidance work: a noise is worth diffusion guidance (ICLR 2026).
Identity, pose, and video. Pose-robust and identity-preserving generation (DRF ICCV 2025, IDS CVPR 2025, SeAl CVPR 2026) and training-free subject-aware video-to-video personalization (SA-V2V, ECCV 2026). Flow matching with straight-path regularization improves vascular segmentation (MICCAI 2026).
3. Conventional Signal Processing: Views, Neural Fields, and Codes
 |
Classical ideas such as sampling, spectra, and bit-planes make neural models faster, smaller, and exact.
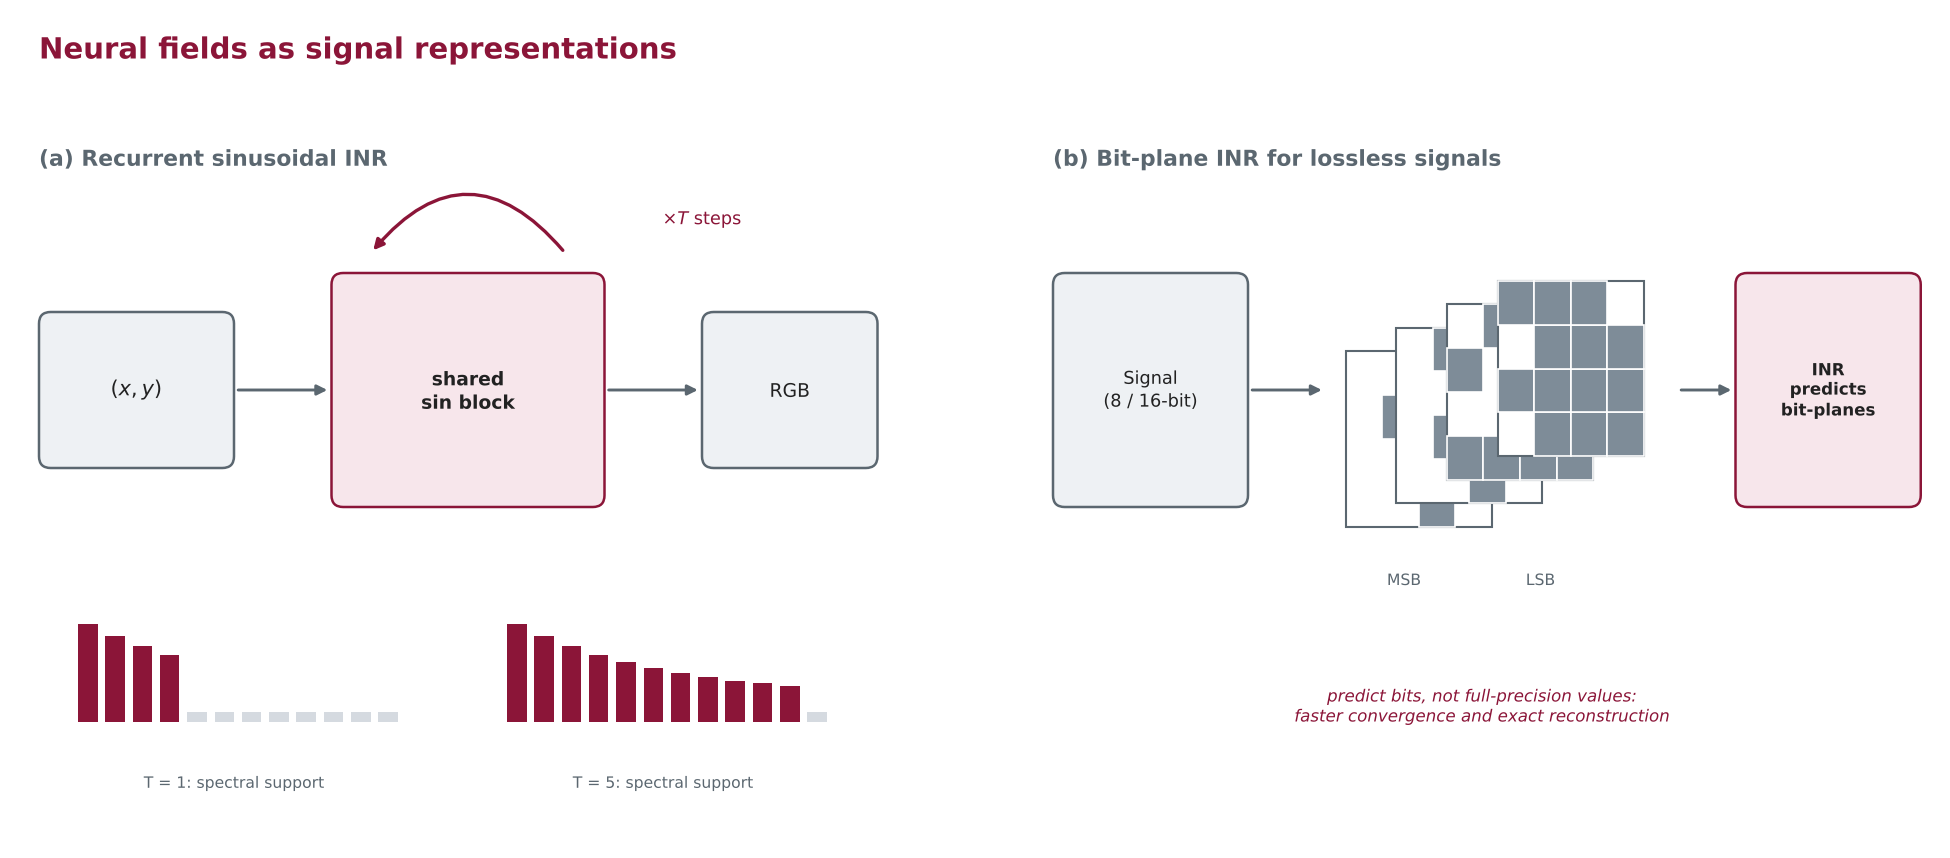
Implicit and recurrent neural representations. Recurrent Sinusoidal INRs (ECCV 2026) reuse one shared sinusoidal block, so every step creates new integer-combination frequencies without adding parameters: at 593.7K parameters, five steps raise PSNR from 39.7 to 63.4 dB (project). Bit-plane decomposition (CVPR 2025) makes INRs lossless, even for 16-bit signals. Recurrent units also help super-resolution (CVPR Findings 2026), and Gaussian rendering gives lightweight arbitrary-scale SR (WACV 2026).
Compression. The JPEG processing neural operator (ICCV 2025) targets backward-compatible coding.
Novel view synthesis with target-oriented multiplane images
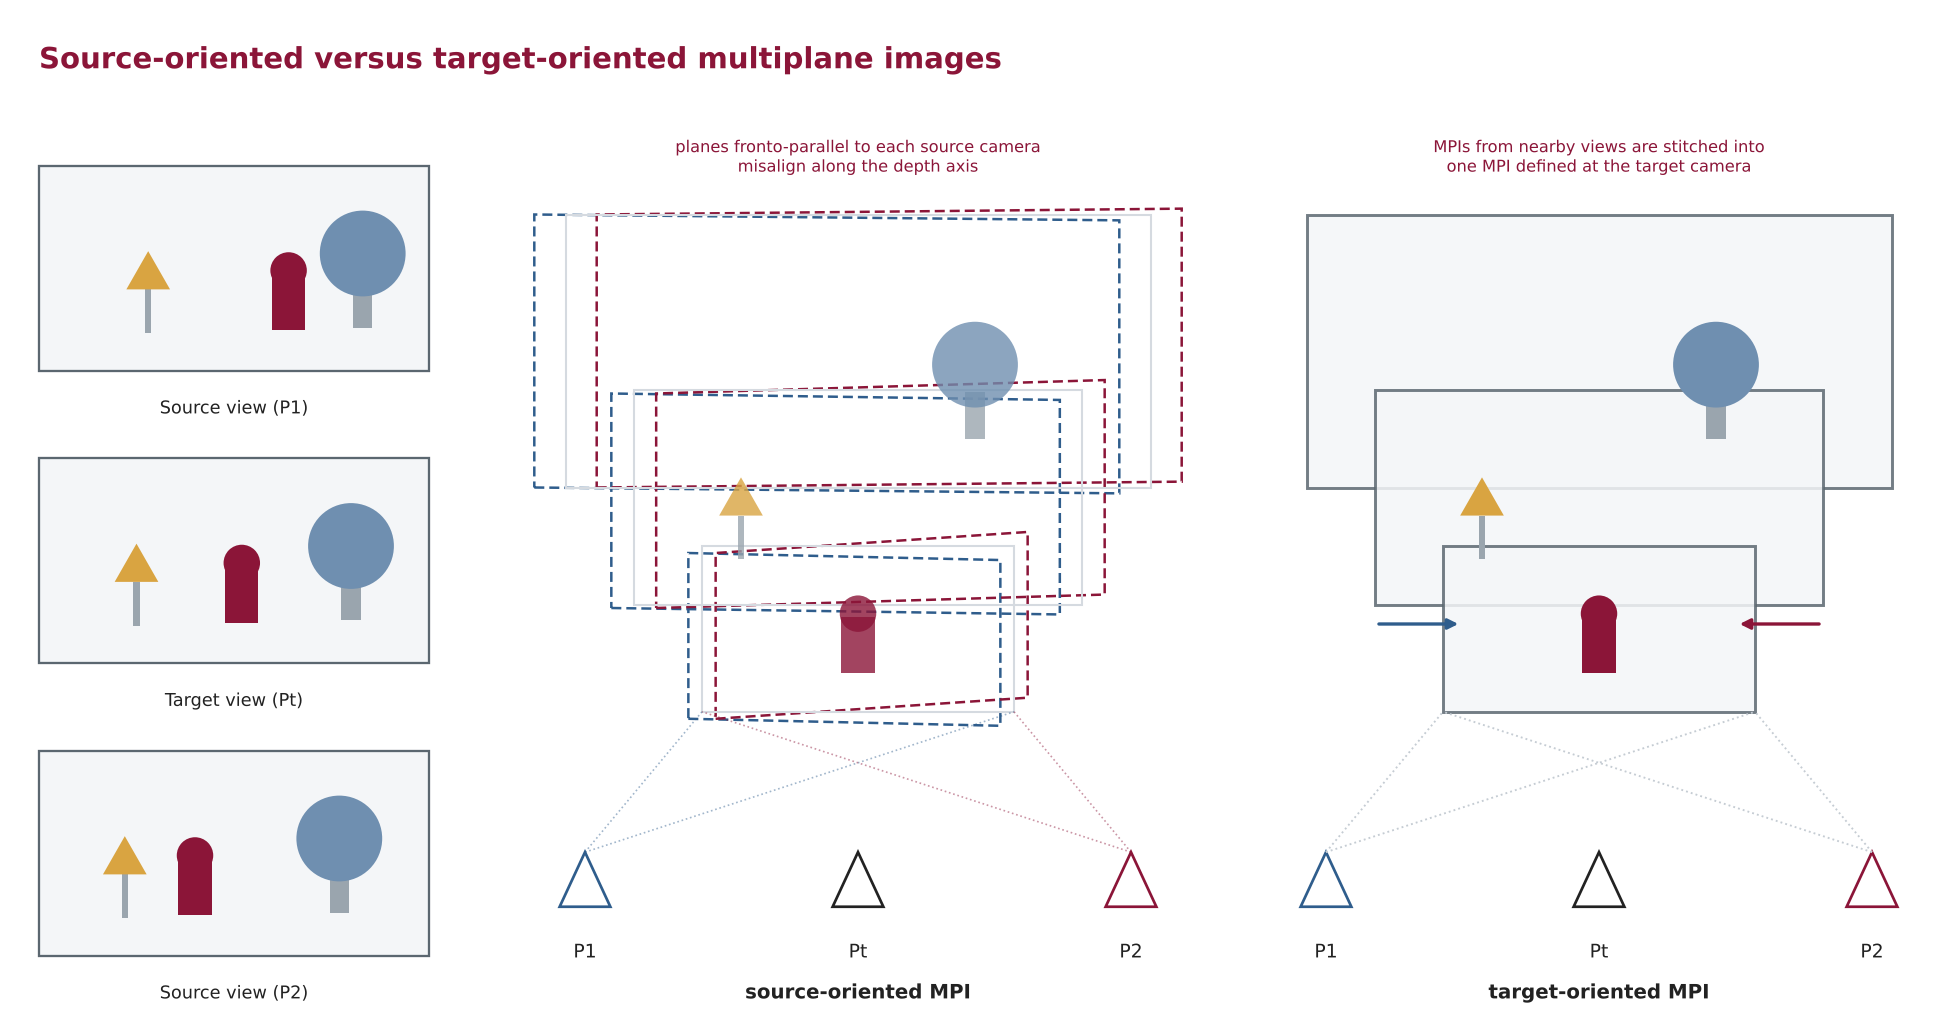 |
A multiplane image (MPI) represents a scene as depth-ordered RGBA planes, but an MPI built at each source camera is fronto-parallel to that camera, so planes from nearby views do not align along depth (figure, middle). Our target-oriented MPI (WACV 2027) stitches the MPIs generated at nearby source cameras P1 and P2 into one MPI defined at the target camera Pt (figure, right). It builds on our continuous image functions LTE (CVPR 2022) and LTEW (ECCV 2022), which estimate local Fourier responses for arbitrary-scale super-resolution and warping.
Optimizers for neural representations: ProPolar
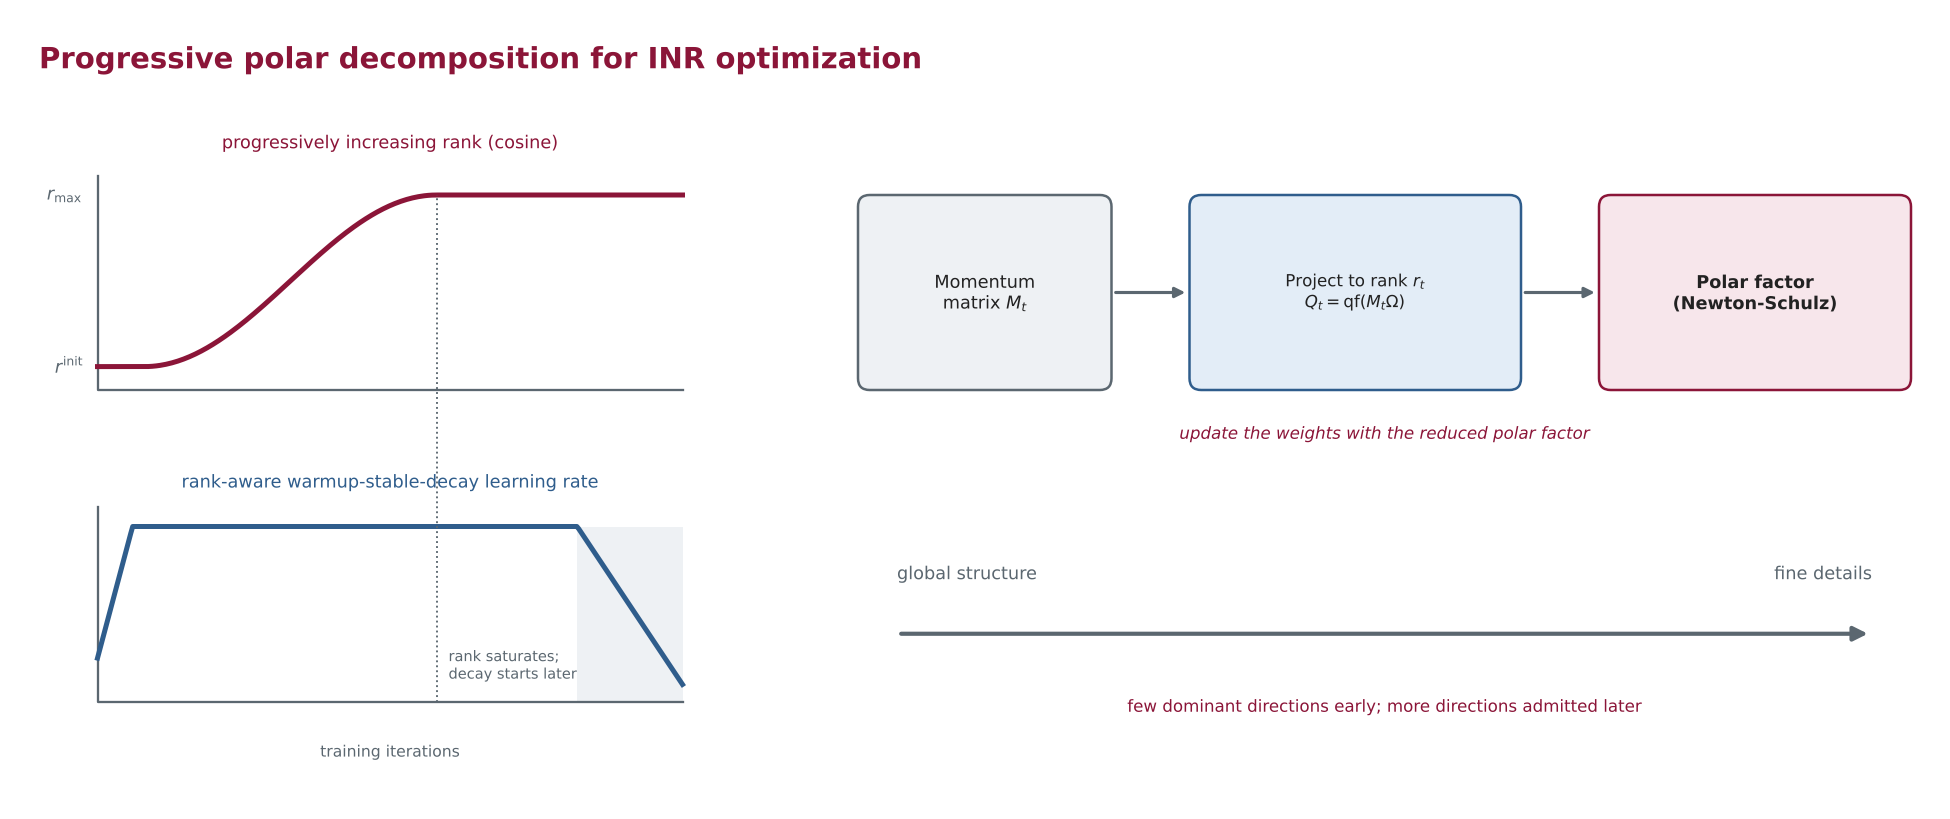 |
Implicit neural representations fit global structure first and fine details later, but standard optimizers keep an update of fixed size. ProPolar (NeurIPS 2026) projects the matrix momentum onto a progressively growing low-rank subspace (cosine rank schedule) and orthogonalizes it there with a polar decomposition, while a rank-aware warmup-stable-decay learning rate holds its peak until the rank saturates. On Kodak a ReLU MLP reaches 28.70 dB versus 22.55 dB with Adam, and on DIV2K 4x super-resolution 23.47 dB versus 22.01 dB with Muon, with sharper NeRF details and gains that persist under equal hyperparameter-search budgets (project).
 Information Processing Algorithm Lab. (IPA)
School of Electrical Engineering, College of Engineering, Korea University
Page generated 2026-10-20 03:59:26 UTC, by jemdoc.